Building AI Features in Modern Web Applications
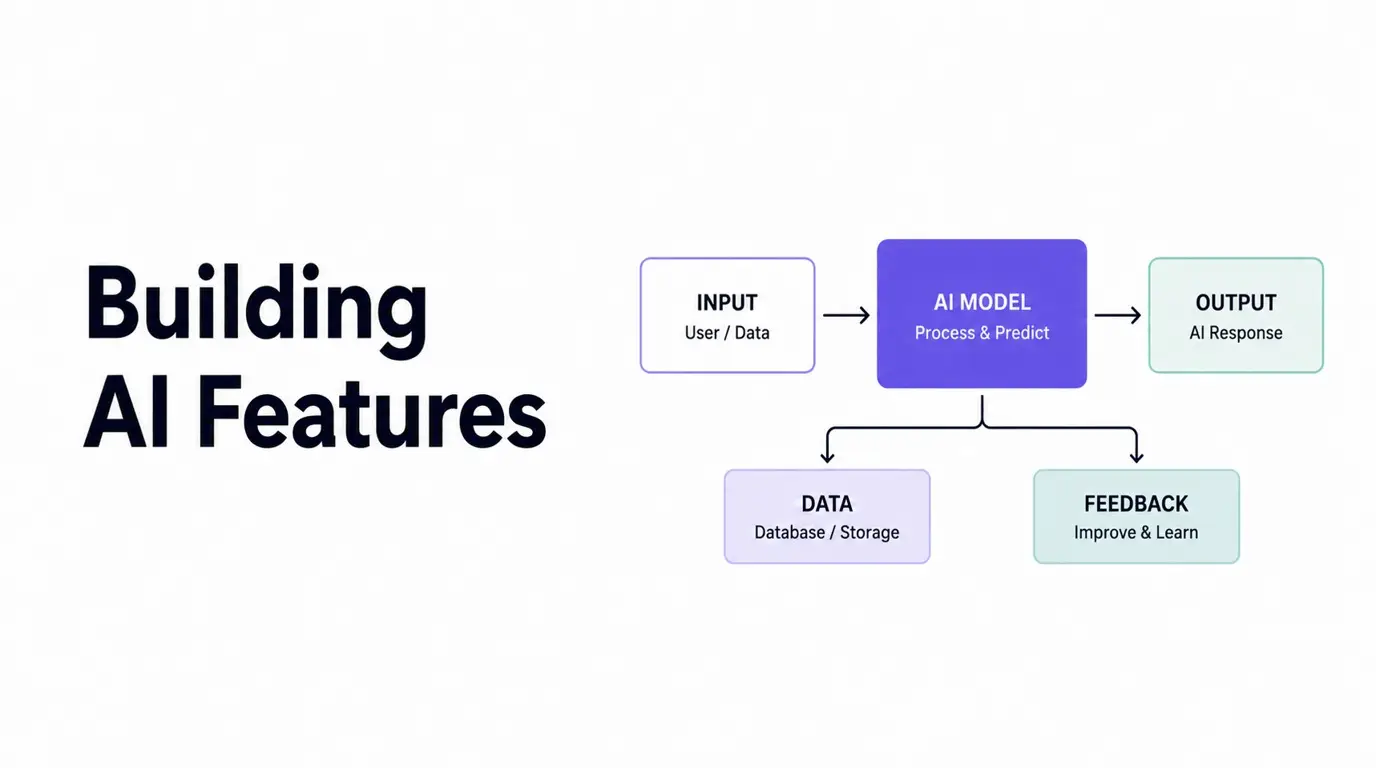
Learn how to build production-grade AI features in React and Next.js applications. Covers streaming responses, structured output with Zod, RAG implementation, semantic search, and rate limiting for AI APIs.
Introduction#
AI features are no longer a differentiator. They are becoming a baseline expectation in consumer and professional software alike. Users expect search that understands intent, content that adapts to context, interfaces that suggest next actions, and tools that automate repetitive work. The question for frontend engineers is not whether to integrate AI into their products, but how to do it in a way that is fast, reliable, and maintainable.
This guide covers the practical patterns and tooling that frontend engineers use to integrate large language models and AI capabilities into production web applications. Not the theory of how LLMs work, but the concrete implementation details that determine whether an AI feature delights users or frustrates them.
1. Streaming First: The Foundation of Good AI UX#
The single most important implementation decision for any AI feature that generates text is streaming. A language model generates tokens one at a time. Without streaming, the user waits for the entire response before seeing anything, which for a paragraph of text can be three to eight seconds. With streaming, the first token appears in under half a second and the user reads as the model writes.
The performance numbers are the same. The perceived performance is completely different. Streaming is not an optimization. It is the baseline user experience for generative AI features.
Server-Side Streaming with the AI SDK#
Vercel’s AI SDK provides the cleanest abstraction for streaming AI responses in Next.js applications. It handles the streaming protocol, error handling, and client-side consumption through a set of React hooks.
// app/api/chat/route.ts
import { streamText } from "ai";
import { openai } from "@ai-sdk/openai";

export const runtime = "edge";

export async function POST(request: Request) {
  const { messages } = await request.json();

  const result = streamText({
    model: openai("gpt-4o"),
    system: `You are a helpful assistant for a software documentation platform.
             Be concise, accurate, and use code examples where appropriate.`,
    messages,
    maxTokens: 1000,
  });

  return result.toDataStreamResponse();
}
Client-Side Consumption with useChat#
"use client";

import { useChat } from "ai/react";
import { useRef, useEffect } from "react";

export function ChatInterface() {
  const bottomRef = useRef<HTMLDivElement>(null);

  const { messages, input, handleInputChange, handleSubmit, isLoading } = useChat({
    api: "/api/chat",
    onError: (error) => {
      console.error("Chat error:", error);
    },
  });

  useEffect(() => {
    bottomRef.current?.scrollIntoView({ behavior: "smooth" });
  }, [messages]);

  return (
    <div className="flex flex-col h-full">
      <div className="flex-1 overflow-y-auto p-4 space-y-4">
        {messages.map((message) => (
          <div
            key={message.id}
            className={message.role === "user" ? "text-right" : "text-left"}
          >
            <div className={`inline-block p-3 rounded-lg max-w-prose ${
              message.role === "user"
                ? "bg-blue-500 text-white"
                : "bg-gray-100 text-gray-900"
            }`}>
              {message.content}
            </div>
          </div>
        ))}
        {isLoading && (
          <div className="text-left">
            <div className="inline-block p-3 rounded-lg bg-gray-100">
              <span className="animate-pulse">Thinking...</span>
            </div>
          </div>
        )}
        <div ref={bottomRef} />
      </div>

      <form onSubmit={handleSubmit} className="p-4 border-t">
        <div className="flex gap-2">
          <input
            value={input}
            onChange={handleInputChange}
            placeholder="Ask anything..."
            disabled={isLoading}
            className="flex-1 p-2 border rounded-lg"
          />
          <button
            type="submit"
            disabled={isLoading || !input.trim()}
            className="px-4 py-2 bg-blue-500 text-white rounded-lg disabled:opacity-50"
          >
            Send
          </button>
        </div>
      </form>
    </div>
  );
}
2. Structured Output for Reliable AI Responses#
Asking a language model to return free-form text is appropriate for conversational interfaces. For features where the application needs to act on the model’s response, such as extracting data, generating form values, or classifying content, you need structured output.
Structured output constrains the model to return JSON that matches a schema you define. When combined with Zod, you get both the constrained output and TypeScript type inference for free.
// app/api/extract/route.ts
import { generateObject } from "ai";
import { openai } from "@ai-sdk/openai";
import { z } from "zod";

const TaskSchema = z.object({
  tasks: z.array(
    z.object({
      title:    z.string().describe("Short, actionable task title"),
      priority: z.enum(["high", "medium", "low"]).describe("Task priority"),
      dueDate:  z.string().nullable().describe("Due date in YYYY-MM-DD format, or null if not specified"),
      assignee: z.string().nullable().describe("Person assigned to the task, or null"),
    })
  ),
  summary: z.string().describe("One sentence summary of all tasks"),
});

export type TaskList = z.infer<typeof TaskSchema>;

export async function POST(request: Request) {
  const { meetingNotes } = await request.json();

  const { object } = await generateObject({
    model:  openai("gpt-4o"),
    schema: TaskSchema,
    prompt: `Extract all action items and tasks from the following meeting notes.
             Be thorough and capture every commitment made.

             Meeting notes:
             ${meetingNotes}`,
  });

  return Response.json(object);
}
"use client";
import { useState } from "react";
import type { TaskList } from "@/app/api/extract/route";
export function MeetingNotesExtractor() {
const [notes, setNotes] = useState("");
const [tasks, setTasks] = useState<TaskList | null>(null);
const [loading, setLoading] = useState(false);
async function extractTasks() {
setLoading(true);
try {
const response = await fetch("/api/extract", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ meetingNotes: notes }),
});
const data = await response.json();
setTasks(data);
} finally {
setLoading(false);
}
}
return (
<div>
<textarea
value={notes}
onChange={(e) => setNotes(e.target.value)}
placeholder="Paste meeting notes here..."
rows={8}
/>
<button onClick={extractTasks} disabled={loading || !notes.trim()}>
{loading ? "Extracting..." : "Extract Tasks"}
</button>
{tasks && (
<div>
<p>{tasks.summary}</p>
<ul>
{tasks.tasks.map((task, i) => (
<li key={i}>
<strong>{task.title}</strong> ({task.priority})
{task.assignee && <span> | {task.assignee}</span>}
</li>
))}
</ul>
</div>
)}
</div>
);
}3. Retrieval-Augmented Generation#
Large language models have a knowledge cutoff and no access to your private data. Retrieval-Augmented Generation (RAG) solves this by retrieving relevant documents from your own data sources and including them in the model’s context window before generating a response.
RAG is the pattern behind features like documentation search that understands questions, customer support bots that reference your knowledge base, and code assistants that are aware of your codebase conventions.
Basic RAG Implementation#
// lib/rag.ts
import { openai } from "@ai-sdk/openai";
import { embed } from "ai";
import { neon } from "@neondatabase/serverless";

const sql = neon(process.env.DATABASE_URL!);

// Step 1: Embed and store documents at index time
export async function indexDocument(content: string, metadata: object) {
  const { embedding } = await embed({
    model: openai.embedding("text-embedding-3-small"),
    value: content,
  });

  await sql`
    INSERT INTO documents (content, metadata, embedding)
    VALUES (${content}, ${JSON.stringify(metadata)}, ${JSON.stringify(embedding)}::vector)
  `;
}

// Step 2: Retrieve relevant documents at query time
export async function retrieveRelevantDocs(query: string, topK: number = 5) {
  const { embedding } = await embed({
    model: openai.embedding("text-embedding-3-small"),
    value: query,
  });

  const docs = await sql`
    SELECT content, metadata,
           1 - (embedding <=> ${JSON.stringify(embedding)}::vector) AS similarity
    FROM documents
    ORDER BY embedding <=> ${JSON.stringify(embedding)}::vector
    LIMIT ${topK}
  `;

  return docs;
}
// app/api/docs-chat/route.ts
import { streamText } from "ai";
import { openai } from "@ai-sdk/openai";
import { retrieveRelevantDocs } from "@/lib/rag";
export const runtime = "edge";
export async function POST(request: Request) {
const { messages } = await request.json();
const lastMessage = messages[messages.length - 1].content;
// Retrieve relevant documents for the user's question
const docs = await retrieveRelevantDocs(lastMessage);
const context = docs
.map((doc: { content: string }) => doc.content)
.join("\n\n---\n\n");
const result = streamText({
model: openai("gpt-4o"),
system: `You are a helpful documentation assistant.
Answer questions based on the following documentation context.
If the answer is not in the context, say so clearly.
Context:
${context}`,
messages,
});
return result.toDataStreamResponse();
}4. AI-Powered Search#
Traditional search matches keywords. Semantic search matches meaning. A user searching for “how do I reset my password” should find results about account recovery, even if none of them contain the exact phrase “reset my password.”
// app/api/search/route.ts
import { embed } from "ai";
import { openai } from "@ai-sdk/openai";
import { neon } from "@neondatabase/serverless";

export const runtime = "edge";

const sql = neon(process.env.DATABASE_URL!);

export async function GET(request: Request) {
  const { searchParams } = new URL(request.url);
  const query = searchParams.get("q");

  if (!query) return Response.json({ results: [] });

  const { embedding } = await embed({
    model: openai.embedding("text-embedding-3-small"),
    value: query,
  });

  const results = await sql`
    SELECT
      id, title, excerpt, url,
      1 - (embedding <=> ${JSON.stringify(embedding)}::vector) AS relevance
    FROM articles
    WHERE 1 - (embedding <=> ${JSON.stringify(embedding)}::vector) > 0.7
    ORDER BY embedding <=> ${JSON.stringify(embedding)}::vector
    LIMIT 10
  `;

  return Response.json({ results });
}
5. Rate Limiting and Cost Control#
AI API calls are expensive. A production AI feature without rate limiting and cost controls can generate unexpected infrastructure bills and degrade the experience for all users when one user makes excessive requests.
// middleware.ts: Rate limiting for AI endpoints
import { NextRequest, NextResponse } from "next/server";
import { Redis } from "@upstash/redis";
import { Ratelimit } from "@upstash/ratelimit";

const ratelimit = new Ratelimit({
  redis: Redis.fromEnv(),
  limiter: Ratelimit.slidingWindow(10, "1 m"), // 10 requests per minute
  analytics: true,
});

export async function middleware(request: NextRequest) {
  if (!request.nextUrl.pathname.startsWith("/api/ai")) {
    return NextResponse.next();
  }

  const userId = request.headers.get("x-user-id") ?? request.ip ?? "anonymous";
  const { success, limit, remaining, reset } = await ratelimit.limit(userId);

  if (!success) {
    return new Response(
      JSON.stringify({
        error: "Too many requests. Please wait before sending another message.",
        resetAt: new Date(reset).toISOString(),
      }),
      {
        status: 429,
        headers: {
          "Content-Type":    "application/json",
          "X-RateLimit-Limit":     String(limit),
          "X-RateLimit-Remaining": String(remaining),
          "X-RateLimit-Reset":     String(reset),
        },
      }
    );
  }

  return NextResponse.next();
}
6. Optimistic UI for AI Actions#
AI responses take time. Users who click a button and see nothing for two seconds assume the action did not register and click again. Optimistic UI updates immediately with a provisional result while the AI processes the request, and reconciles the actual result when it arrives.
"use client";

import { useOptimistic, useState } from "react";

type Message = { role: "user" | "assistant"; content: string; id: string };

export function OptimisticChat() {
  const [messages, setMessages] = useState<Message[]>([]);
  const [optimisticMessages, addOptimistic] = useOptimistic(
    messages,
    (state, newMessage: Message) => [...state, newMessage]
  );

  async function sendMessage(formData: FormData) {
    const content = formData.get("message") as string;
    if (!content.trim()) return;

    const userMessage: Message = {
      id:      crypto.randomUUID(),
      role:    "user",
      content,
    };

    // Show user message immediately
    addOptimistic(userMessage);
    setMessages((prev) => [...prev, userMessage]);

    const response = await fetch("/api/chat", {
      method: "POST",
      body: JSON.stringify({ messages: [...messages, userMessage] }),
    });

    const assistantMessage: Message = {
      id:      crypto.randomUUID(),
      role:    "assistant",
      content: await response.text(),
    };

    setMessages((prev) => [...prev, assistantMessage]);
  }

  return (
    <div>
      {optimisticMessages.map((msg) => (
        <div key={msg.id}>
          <strong>{msg.role}:</strong> {msg.content}
        </div>
      ))}
      <form action={sendMessage}>
        <input name="message" placeholder="Type a message..." />
        <button type="submit">Send</button>
      </form>
    </div>
  );
}Conclusion#
Integrating AI into frontend applications is no longer an advanced specialization. It is becoming a standard part of the frontend engineer’s toolkit. The patterns in this guide, streaming responses, structured output with Zod, RAG for private data, semantic search, rate limiting, and optimistic UI, cover the majority of production AI feature implementations.
The technical complexity of calling an AI API is low. The craft is in the user experience: making responses feel fast through streaming and optimistic updates, making them reliable through structured output and error handling, and making them safe through rate limiting and cost controls.
Build AI features the same way you build any other feature: with the user’s experience as the primary concern and reliability as a non-negotiable requirement.